Beyond AI and beyond the web, at once
Each claim is checked against what a capable language model would say unprompted and against the published web. Only what passes both is yours.
The only score that measures what a piece adds beyond what AI already knows and what is already published. Claim by claim, with the reasons, in any language.
Free to start: ten quick reads with your email. Full verdicts from a dollar.
See an example resultAny language, 120 to 6,000 words.
Each statement is checked for whether it brings anything new, and how well it holds up.
Your own contributions, credibility and effort, with the reasons.
AI detectors ask who typed the words. Plagiarism checkers match strings. SEO graders count the terms of pages that already rank. Verdict asks the question editors and readers actually ask: does this piece add anything?
Each claim is checked against what a capable language model would say unprompted and against the published web. Only what passes both is yours.
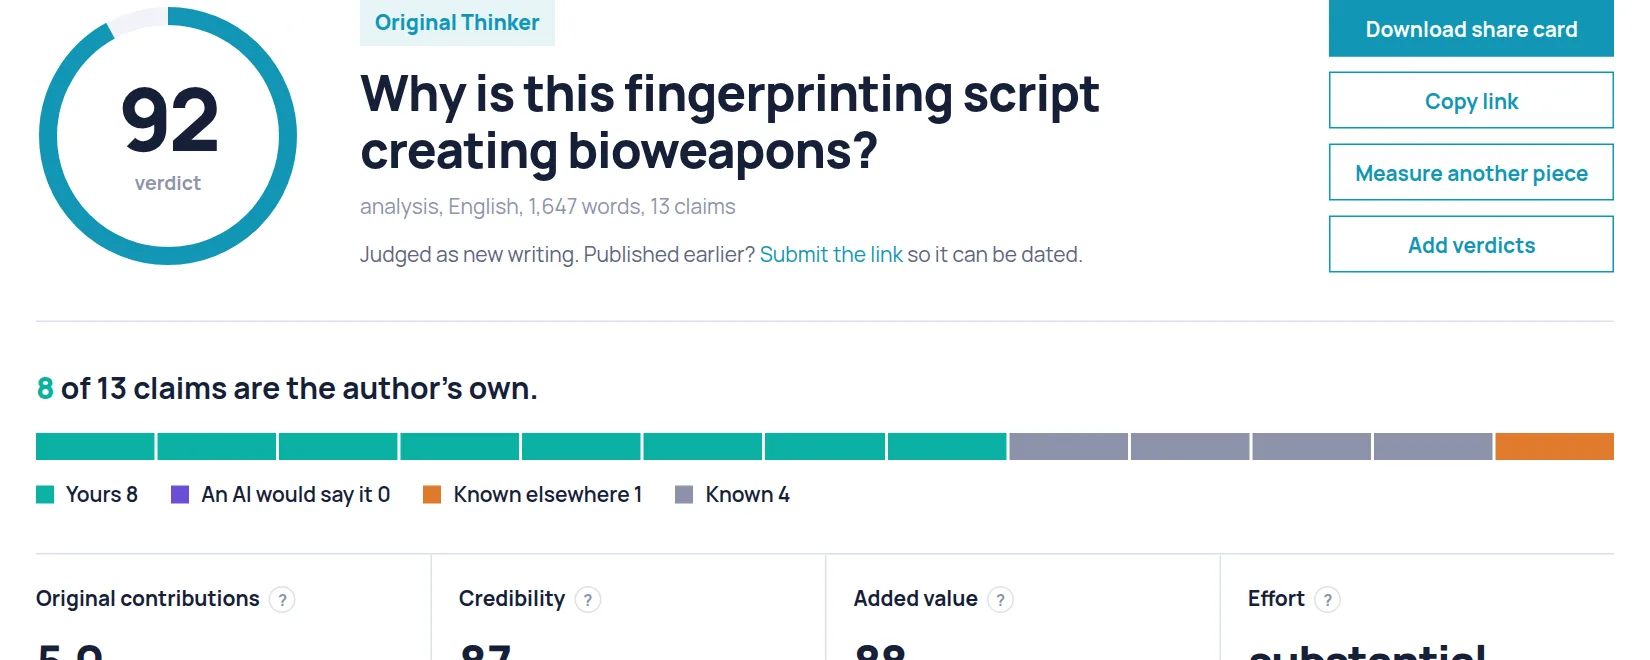
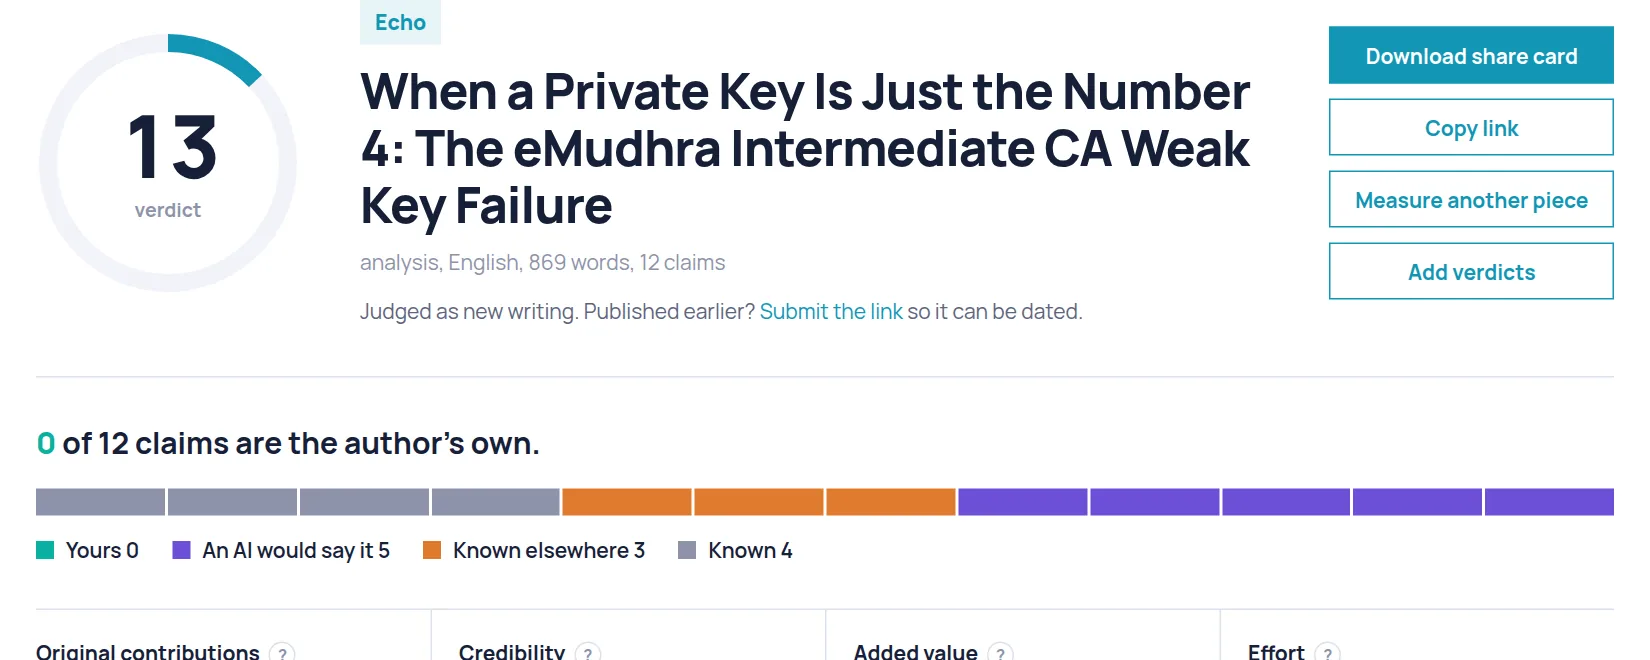
Every claim is marked yours, something any AI would say, known elsewhere or common knowledge, with its credibility and a note. You can argue with it, line by line.
Invented statistics and unsourced figures earn almost nothing; in our test they cost four points. New only counts when it holds up.
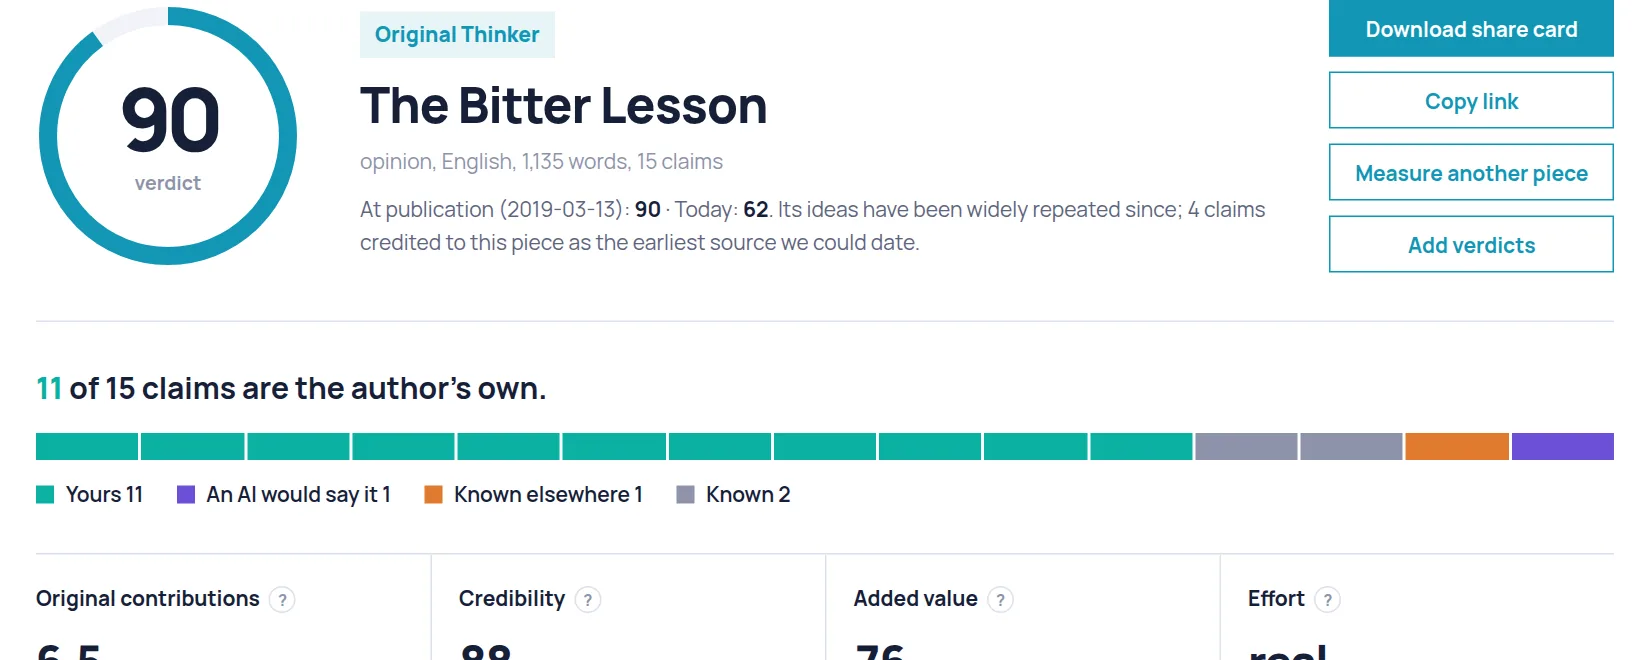
A piece that was first is credited as the source of the ideas that spread from it, with today's reading shown beside the original.
Side by side: Originality.ai, GPTZero, Copyscape, Turnitin, Grammarly, Surfer SEO.
Verdict is built on what Google's quality raters are told to reward, what editors look for and what readers notice: originality, effort, accuracy and first-hand experience. A low verdict means the piece will be read as an echo of what is already out there, however well it is written. A high one means it is a source.
Every verdict comes with the claim view and, when you ask, concrete suggestions to raise it: what to source, what to cut, where to add what only you know.
Community Edition, Apache 2.0
The quick read, the benchmark that produced every number on this page, the API clients, the WordPress plugin and the MCP integration are open. Run the quick read on your own machine, reproduce our results, or build on the API. The hosted verdict pays for the model work; the community keeps it honest.
# Run the quick read locally, no key, no model
git clone https://github.com/expulp/verdict && cd verdict
pip install -e .
verdict-quick read https://example.com/essay   # one piece, in your terminal
verdict-quick serve --port 8080                # or the same API on your own host

# Reproduce the benchmark against the hosted verdict
python -m benchmark.assemble && python -m benchmark.report scores.csv
The quick-read engine (sentence echo map, predictability, provenance checks), the benchmark harness and every result table, the Python and JavaScript clients, the WordPress plugin, the MCP setup.
The claim judge, its prompts and weights, and the corpus of earlier submissions that protects first publishers. That is what a verdict pays for, and what keeps the score hard to game.
Open an issue with a piece the verdict got wrong; it goes into the calibration set. Add test pairs in your language. Build a client or an editor plugin. Contributors get verdicts on the house.
What's already online, sentence by sentence. How distinctive the wording is. Hidden characters. A provisional score. Ten per account, unlimited once you've bought anything.
Read a pieceEvery claim marked as yours, known, or already online, with its credibility, the effort the piece shows, and a verdict you can share.
Score drafts before publishing, audit an archive, gate submissions. Verdicts bought here work on the API too. Batch mode and publisher plans are next.
API referenceVerdicts are valid for 90 days. Payments by Stripe: cards, Apple Pay and Google Pay.
150 verdicts a month. Emailed reports and share cards.
600 verdicts a month. Full API access and batch mode.
3,000 verdicts a month. Badge and plugin, team keys.
Monthly verdicts are added on each payment and stay valid for 90 days. Cancel any time from your account.
Verdict is in early access. It is a reading with reasons, not a certificate. Everything below was measured on 638 pieces the tool was never tuned on; the full tables are in the open repository.
Real essay vs an AI article on the same topic. The essay scores higher in 80% of pairs, by 22 points on average.
Invented statistics don't pay. Five fake figures added to an AI article lowered its score by 4 points on average. A scorer that rewards "new facts" without checking them shows the opposite.
Paraphrased copies are caught. A rewrite of a piece already analysed is flagged as a restatement, with the original's date.
Personal essays and how-tos. After the genre work, the author's piece beat its AI twin in every pair, by 29 and 46 points.
Older pieces are read as of their date. Ideas that spread afterwards are credited to the piece, with today's reading shown beside it.
Any language. The free quick read uses no model at all.
No human ratings yet. "Excellent" in our test means essays that reached the Hacker News front page, which measures interest, not originality. Some of the 1-in-5 misses may be right.
Run-to-run noise. Near a tier boundary, two runs can land on different labels. Read the claims, not only the number.
Accurate but thinly indexed facts read as new. A machine rewrite of real local news, with facts our search does not find, can score well.
Search recall is weaker outside English and on small blogs, so "known elsewhere" is a floor, not a census.
Fiction is experimental. Weighing observations claim by claim does not yet separate a human story from a competent AI one; fiction results carry a notice.
Pasted text is judged as new. Submit the link if the piece was published earlier, so it can be dated.
Verdicts that fail are not charged. If a result looks wrong, reply to any email from us with the link: every disputed case goes into the calibration set.
AI detectors and watermarks ask who typed the words. Readers, editors and search engines ask whether the piece adds anything. Verdict measures the second.
Anthropic began watermarking Claude's text in August 2026, with a statistical signal in word choice rather than hidden characters. Google's SynthID detector opened to the public in October 2026, for images, video and audio.
Neither tells you whether the ideas are the author's. A watermark survives in a piece a writer merely proofread with AI, and vanishes from an AI draft that was reworded by hand. Anthropic's own explainer lists the cases where the mark breaks down and says it cannot prove authorship. For text, no vendor offers a public detector yet: Anthropic has announced one, Google's covers other media, and OpenAI marks images only.
Sources: BleepingComputer on Anthropic's text watermark, The Decoder on the announced detection API, eWeek on the SynthID Detector launch, Google's SynthID documentation.
Detectors are classifiers trained on how machines tend to phrase things. Vendors report near-zero error rates on their own benchmarks; independent tests find accuracy falling on edited or paraphrased text.
A Stanford study found seven detectors flagged the majority of essays by non-native English speakers as machine-written while classifying native speakers' essays almost perfectly. As more people write with AI assistance, "was a model involved" stops separating good work from filler. A piece can be written entirely by hand and say nothing new, or drafted with help and carry a real finding.
Sources: Liang et al., GPT detectors are biased against non-native English writers (2023), Pangram Labs technical report on its classifier (2024).
Google's Search Quality Rater Guidelines tell raters to give the lowest rating when the main content is copied, paraphrased or AI-generated with little effort, originality or added value. Verdict is anchored on the same criteria.
The guidelines define originality as content "not available on other websites" and effort as the extent to which "a human being actively worked to create satisfying content". They name the tells of paraphrased content: only commonly known information, heavy overlap with reference sites, or a summary of one page with nothing added. Google also holds a patent on scoring a document by the information it adds beyond what the reader has already seen.
Sources: Google Search Quality Rater Guidelines (PDF, sections 3.2 and 4.6), Search Engine Land on the January 2025 update, Google patent US20200349181A1, contextual estimation of link information gain.
Recent work shows that language models converge on the same points and that human writing adds more new ideas per piece, and gives ways to measure novelty and factual support claim by claim.
Wenger and Kenett found answers from different models far more alike than answers from different people. Lu et al. introduced a Creativity Index that measures how much of a text can be rebuilt from existing web text, and found human writing scored far higher. Document-level novelty metrics such as NovAScore score a piece by its atomic facts, and Google DeepMind's long-form factuality work checks each fact against search. Verdict draws on this line of research without being a copy of any one method.
Sources: Wenger and Kenett, creative homogeneity across LLMs (2025), Lu et al., AI as Humanity's Salieri, ICLR 2025, NovAScore, COLING 2025, Wei et al., long-form factuality in LLMs (2024), Measuring information potential in text corpora (2025).
| Expulp Verdict | AI detectors | Plagiarism checkers | SEO content graders | |
|---|---|---|---|---|
| The question answered | Does this piece add anything beyond what's known and published? | Was this written by a machine? | Is this text copied? | Does it cover what already ranks? |
| Still meaningful when people write with AI help | Yes | No, by design | Yes | Yes |
| Reasons, claim by claim | Yes | Sentence-level probability | Matched passages | Term coverage |
| Catches paraphrased ideas, not only copied words | Yes | Not its job | Rarely | No |
| Rewards invented facts as "new" | No, unverified figures earn little | Not scored | Not scored | Often, difference reads as gain |
| Languages | Any | Mostly English | Many | Several |
Examples of each category: GPTZero, Pangram and Originality.ai; Copyscape and Turnitin; Surfer and Clearscope. Based on each product's public documentation, October 2026. Detail: vs AI detectors, vs plagiarism checkers, vs SEO graders, vs writing assistants.
Score drafts before you publish, audit a back catalogue, gate submissions, or run hundreds of pieces as one batch. Your verdicts work on the API with the key from your account.
# Free quick read (no key)
curl -X POST https://verdict.expulp.com/v1/quick \
  -H "Content-Type: application/json" -d '{"url": "https://example.com/essay"}'

# Full verdict (one credit), then poll until status is "done"
curl -X POST https://verdict.expulp.com/v1/verdicts \
  -H "X-API-Key: oi_your_key" -H "Content-Type: application/json" \
  -d '{"url": "https://example.com/essay", "notify": true}'
curl https://verdict.expulp.com/v1/verdicts/Q2x… -H "X-API-Key: oi_your_key"
# → {"status":"done","result":{"score":74,"tier":{"label":"Fresh Voice"},"verdict":"…","claims":[…]}}